Commit Graph

57726 Commits

Author SHA1 Message Date
Driss Guessous dcafe3f271 Updates to the release notes scripts and documentation (#94560)
# Summary
This PR made some significant changes to the scripts around Release Scripts. At a high level:
- Turned the quips into docs and updated links
- Update the common.categorizes list in the hopes to make this the source of truth for releases- This is hard since the release_notes labels can be changed at will. An alternative would be to poll from github api. However, I think that is overkill. The notebook does a set compare and will show you knew categories. I think we want this to be manual so that the release note engineer will decided how to categorize.
- Create cateogry group from speaking with folks on distributed and AO that told me these different release categories can be merged.
- I am the newest person to Core and don't use ghstack soo made token getting a lil more generic.
- Added a classifier.py file. This file will train a commit categorizer for you, hopefully with decent accuracy. I was able to achieve 75% accuracy. I drop the highest frequency class - "skip" since this creates a more useful cateogrizer.
- I updated the categorize.py script so that the prompt will be what the classifier thinks, gated by a flag.
- Added a readme that will hopefully help future release notes engineers.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/94560
Approved by: https://github.com/albanD
2023-03-16 00:09:26 +00:00
Will Constable 731bb6e61b Fix periodic job by excluding check_graph_breaks (try 2) (#96803)
**note about second try**
First try (https://github.com/pytorch/pytorch/pull/96780) was reverted because while it fixed periodic,
it broke inductor cpu-accuracy (which strangely didn't show up as failures on this PR).  This try keeps the cpu-accuracy filter and also adds the inductor filter to get rid of periodic jobs.

**the actual PR desc**
It's going to be harder to properly support check_graph_breaks across multiple baselines.

Periodic and Inductor workflows are different baselines since they include different sets of models.

It's not as simple as checking in the csv for the superset (periodic), becuase update_expected.py is designed to run given the sha of your failing PR and reset the baseline to that PR's artifacts. This is a nice workflow, and would be harder to manage if it had to always point to a periodic job.

For now just do the check on the inductor job and ignore the other models covered only on periodic.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96803
Approved by: https://github.com/desertfire
2023-03-15 23:24:47 +00:00
mingfeima 6d62134f2c fix aminmax output resize issue when input is a zero dimension tensor (#96171)
Fix https://github.com/pytorch/pytorch/issues/96042

### before
```
>>> torch.aminmax(torch.tensor(1, device='cpu'), dim=0, keepdim=True)
__main__:1: UserWarning: An output with one or more elements was resized since it had shape [], which does not match the required output shape [1]. This behavior is deprecated, and in a future PyTorch release outputs will not be resized unless they have zero elements. You can explicitly reuse an out tensor t by resizing it, inplace, to zero elements with t.resize_(0). (Triggered internally at ../aten/src/ATen/native/Resize.cpp:24.)
torch.return_types.aminmax(
min=tensor([1]),
max=tensor([1]))
>>> torch.aminmax(torch.tensor(1, device='cpu'), dim=0, keepdim=False)
torch.return_types.aminmax(
min=tensor(1),
max=tensor(1))
```
### after
```
>>> torch.aminmax(torch.tensor(1, device='cpu'), dim=0, keepdim=True)
torch.return_types.aminmax(
min=tensor(1),
max=tensor(1))
>>> torch.aminmax(torch.tensor(1, device='cpu'), dim=0, keepdim=False)
torch.return_types.aminmax(
min=tensor(1),
max=tensor(1))

```

Marked the following test as expected_fail:
`test_vmap.py TestVmapOperatorsOpInfoCPU.test_op_has_batch_rule_aminmax_cpu_float32`

Given input shape of (2), the loop out is shape (2), the batched vmap out is (2, 1), which mismatched.
The loop out will calculate twice on a tensor shape of ( ): without this patch, the output is (1), and then stacked into (2, 1); with this patch, the output is ( ), then stacked into (2).

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96171
Approved by: https://github.com/jgong5, https://github.com/ngimel, https://github.com/zou3519
2023-03-15 22:44:13 +00:00
albanD 7c525823c7 Remove un-used list. And disable pytest for public binding test. (#96684)
This contains a temporary change to make sure the test fails nicely now.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96684
Approved by: https://github.com/clee2000
2023-03-15 22:12:00 +00:00
soulitzer f3db2a6341 Expose API to specify custom context manager for checkpoint (#96783)
Per [design](https://docs.google.com/document/d/1v-yqRqiWA6dIUOw5OpqFs2PqSQIbDEkwRPGk9FcYnxg/edit) we want (1) to allow the user to pass in a function that returns two context managers (2) a per-call API only for now, and (3) do not upstream selective checkpoint for the short term.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96783
Approved by: https://github.com/albanD
2023-03-15 20:37:33 +00:00
Howard Huang ac7329b323 Add exceptionhandler to more distributed_c10d APIs (#96770)
Summary: Adding exception handler to a few more APIs so that internal errors are logged to the c10d errors scuba table

Test Plan: sandcastle

Differential Revision: D44068557

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96770
Approved by: https://github.com/wz337
2023-03-15 20:31:46 +00:00
Xiao Wang 1716709d46 [CUDA] Use accumulate type to improve accuracy of grid_sample on half precision inputs [v2] (#96586)
Fixes #96429

This PR is also a follow up for #90427. In that PR, we also discussed whether calculations of grid indices `grid_sampler_compute_source_index` should also be upcasted to `opmath_t` https://github.com/pytorch/pytorch/pull/90427/files#r1048876708. Due to another unit test failure, we didn't upcast those calculations in that PR.

After some investigations, I found that the inaccurate results have nothing to do with the internals of `affine_grid`, even if it's calculated using `double` internally. As long as input `grid` is passed to `grid_sample` in **half** precision, the results will be less inaccurate than a **float** `grid`. This can be verified with a short C++ program like this (by setting `TYPE_T` to `__half` and `float` in compilations)

```cpp
#include <cuda.h>
#include <cuda_runtime.h>
#include <cuda_fp16.h>

#include <iostream>

#ifndef TYPE_T
    #define TYPE_T float
#endif

int main() {
    using type_t = TYPE_T;
    type_t d = static_cast<__half>((double)2.0 / 3.0);
    type_t s = (((float)d + 1.f) * 3 - 1) / 2;

    printf("%.15f %.15f\n", (double)d, (double)s);
}
```

Outputs are
```
./float.out
0.666503906250000 1.999755859375000

./half.out
0.666503906250000 2.000000000000000
```

To resolve the discussion back in https://github.com/pytorch/pytorch/pull/90427/files#r1048876708, I've also increased the test tolerance in the failed unit test `issue_24823_1(torch.half)`.

For the original script in #96429, I got more accurate results with `align_corners = True`
```
align_corners = True
Expected result has mean absolute value of 0.5285 and maximum absolute value of 3.2067.
Half precision result is off by 0.0001 (0.02%) on average and 0.0010 (0.03%) at maximum.

align_corners = False
Expected result has mean absolute value of 0.5189 and maximum absolute value of 3.0101.
Half precision result is off by 0.0001 (0.02%) on average and 0.0010 (0.03%) at maximum.
```
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96586
Approved by: https://github.com/ngimel
2023-03-15 19:25:20 +00:00
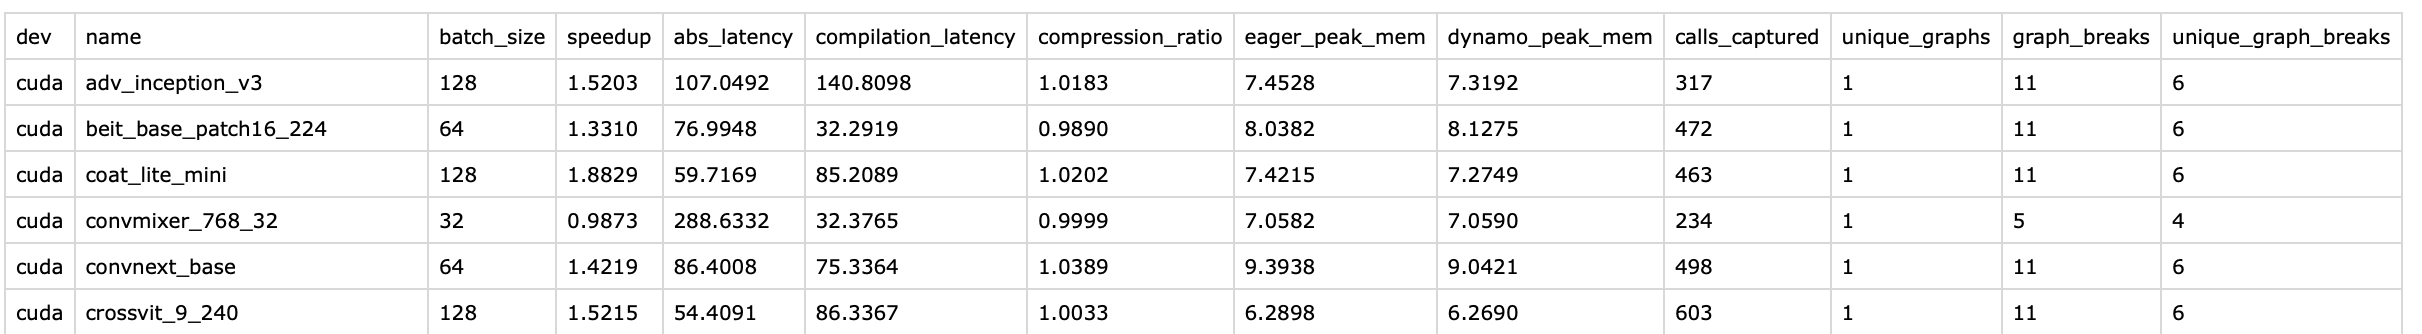
Will Constable 54cd4a67d0 Output peak memory stats from dynamo torchbench perf CI (#95666)
Adds absolute memory usage numbers (in addition to compression ratio) to performance jobs.

Example output:
<img width="1211" alt="image" src="https://user-images.githubusercontent.com/4984825/225419950-500908c5-00ce-4711-afa2-c995bf90d35d.png">

Pull Request resolved: https://github.com/pytorch/pytorch/pull/95666
Approved by: https://github.com/ezyang, https://github.com/williamwen42
2023-03-15 19:24:47 +00:00
Elias Ellison 445863128b Use .to instead of contiguous to generate channels last tensor (#96791)
Fix for https://github.com/pytorch/pytorch/issues/95693.

From https://pytorch.org/tutorials/intermediate/memory_format_tutorial.html:
> There are minor difference between the two APIs to and contiguous. We suggest to stick with to when explicitly converting memory format of tensor.
For general cases the two APIs behave the same. However in special cases for a 4D tensor with size NCHW when either: C==1 or H==1 && W==1, only to would generate a proper stride to represent channels last memory format.

We hit this case in convolution_backward in calling `contiguous()`. Even though we were determining that we should run the backward in channels_last forward, as FakeTensor had gathered from the output of [determine_backend_memory_format](https://github.com/pytorch/pytorch/blob/master/torch/_subclasses/fake_tensor.py#L559), we were still outputting a contiguous tensor. That led to the mismatch in strides in the issue.

Should we be calling `to` instead of `contiguous` more liberally throughout the codebase, especially in convolution related code ? Not sure if there are reasons not to do this.

Another fix would be to update `cudnn_conv_suggest_memory_format` so that it would output a contiguous_format in this case.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96791
Approved by: https://github.com/ngimel
2023-03-15 19:12:04 +00:00
Kshiteej K 24c49dbf14 [functorch] batch rule : few decomposition ops (#96744)
Fixes https://github.com/pytorch/pytorch/issues/96741

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96744
Approved by: https://github.com/zou3519
2023-03-15 18:55:05 +00:00
kshitij12345 9b1b3fdd2d add to functorch codeowner (#96746)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96746
Approved by: https://github.com/zou3519
2023-03-15 18:52:22 +00:00
Stas Bekman 11e708dd6b [doc] fix torch.cuda.mem_get_info doc (#96621)
the current `torch.cuda.mem_get_info` doc is incorrect. This util returns `free, total` and not `free, used`

```
__host__ ​cudaError_t cudaMemGetInfo ( size_t* free, size_t* total )
    Gets free and total device memory.
```

Also this util isn't mentioned in https://pytorch.org/docs/stable/notes/cuda.html#cuda-memory-management - should it be included there as well?
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96621
Approved by: https://github.com/kit1980
2023-03-15 18:11:00 +00:00
Huy Do 6339ee5d23 Temporarily disable test_ops_jit on Windows (#96859)
See https://github.com/pytorch/pytorch/issues/96858
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96859
Approved by: https://github.com/kit1980
2023-03-15 17:51:32 +00:00
Wanchao Liang aa09f8891c add 2d tests to ci (#96711)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96711
Approved by: https://github.com/huydhn, https://github.com/fduwjj
2023-03-15 17:18:47 +00:00
Driss Guessous 5612aa6acd Fixes a layer_norm_nested backwards edge case. (#96788)
# Summary
Add Test and the fix for when input NT doesn't require grad to layernorm.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96788
Approved by: https://github.com/cpuhrsch
2023-03-15 17:16:13 +00:00
Xuehai Pan 80e8e41ca7 Fix type hint for torch.Tensor.grad_fn (#96804)
Fix type hint for `torch.Tensor.grad_fn`, which can be a `torch.autograd.graph.Node` or `None`.

This is a regression in `torch` 2.0. It makes `mypy` failure in downstream projects.

Ref:

- https://github.com/pytorch/pytorch/issues/94937#issuecomment-1469344993
- metaopt/torchopt#149
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96804
Approved by: https://github.com/Skylion007
2023-03-15 17:14:05 +00:00
Elias Ellison a7d2e451fd Fix build, shadowed variable (#96778)
Had an internal build error with this

Differential Revision: [D44071892](https://our.internmc.facebook.com/intern/diff/D44071892)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96778
Approved by: https://github.com/Chillee, https://github.com/voznesenskym
2023-03-15 16:41:06 +00:00
Brian Hirsh e9d9151eec [aot autograd] avoid cloning some inputs unnecessarily when they dont require grad (#96342)
When constructing the joint graph, we normally have to clone any inputs that are mutated, so that we can pass in the original, pre-mutation inputs as leaves to autograd.

Previously, we were doing this for all mutated inputs - but we only need to do it for inputs that require gradients and participate in autograd.

Hopefully this should speed up code like batch norm - I think before this we were unnecessarily cloning the running stats during training.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96342
Approved by: https://github.com/albanD, https://github.com/ezyang
2023-03-15 16:34:04 +00:00
Brian Hirsh 3cd9c7a16d [aot autograd] refactor to make functionalization self-contained (#96341)
This refactor should make it easier to add an export hook into aot autograd.

(1) I killed `create_forward_or_joint_functionalized()` (and the functions that it called, like `forward_or_joint()`) which used to handle autograd + functionalization all-in-one-go for the joint case, and was also used in the inference case.

I added a few separate helper functions:

`create_functionalized_graph()`: this takes a flat fn, and returns a functionalized fx graph. It is mostly just a thin wrapper around functionalization + make_fx(), but also has some extra logic to manually append `copy_()` ops to the end of the graph.

`fn_no_extra_mutations()`: this creates the fn that we want to trace in the inference code path. It takes in a function that it then calls, and returns the outputs + any (updated) mutated inputs.

`joint_fn_no_external_mutations()`: this creates the fn that we want to trace in the joint code path. It takes in a function, and traces out its joint. It also does the work of cloning inputs that are mutated and require gradients, returning mutated inputs as outputs, and returning intermediate bases as outputs

We should be able to add an export hook by basically adding a similar version of `joint_fn_no_external_mutations` but with a lot more restrictions (guaranteed to have no tangents, not synthetic bases, etc), and calling `create_functionalized_graph()` on it.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96341
Approved by: https://github.com/ezyang
2023-03-15 16:34:04 +00:00
Rohan Varma 8e6287264d [Optim in backward] register_hook=False API (#95096)
Use this API to avoid registering hooks for applications that do their
own custom logic. This eliminates the need for DDP to have to de-register these
hooks.

Differential Revision: [D43383794](https://our.internmc.facebook.com/intern/diff/D43383794/)

**NOTE FOR REVIEWERS**: This PR has internal Meta-specific changes or comments, please review them on [Phabricator](https://our.internmc.facebook.com/intern/diff/D43383794/)!
Pull Request resolved: https://github.com/pytorch/pytorch/pull/95096
Approved by: https://github.com/zhaojuanmao
2023-03-15 14:33:13 +00:00
Brian Hirsh 8ce8d49cc4 aot autograd: consolidate metadata (#96340)
Another bonus of factoring the synthetic_base logic into one place: we used to have a `CompiledRuntimeMetadata` object that encapsulated `ViewAndMutationMeta`, plus a bunch of extra synthetic base metadata that was plumbed around. Now I can kill that first metadata object, and use `ViewAndMutationMeta` on its own everywhere.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96340
Approved by: https://github.com/ezyang
2023-03-15 13:45:45 +00:00
Brian Hirsh 070cefaef9 aot_autograd: dont requires_grad on tangents (#96339)
Ed pointed it out a few days ago - I probably added this mistakenly a few months ago. I can't think of any reason it's necessary, and removing it doesn't cause any tests to fail.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96339
Approved by: https://github.com/ezyang
2023-03-15 13:45:45 +00:00
Brian Hirsh a269469982 aot autograd refactor: make all synthetic base logic layered in a single location (#96235)
This  refactor doesn't significantly change LoC in aot autograd, but I think this nets out to making it clearer (interested in peoples' thoughts).

The idea is that I tried to re-write the part of aot autograd that deals with synthetic bases in a layered way, similar to how Ed wrote the logic for dedup'ing inputs: it happens in one place, and all of the downstream transformation in aot autograd don't have to worry about it.

Specifically, I added a new function `aot_wrapper_synthetic_base`, similar to the existing `aot_wrapper_dedupe`.

The benefit: none of the other code in aot autograd needs to think about synthetic bases (previously, synthetic base code was intertwined in several places).

The downsides: there are two.

(1) `aot_wrapper_synthetic_base()` needs to have its own epilogue. There is one particularly hairy case, where factoring the synthetic base logic to a single location was painful: If you have two inputs that alias each other, where one gets a data mutation, and the other gets a metadata mutation.

Ordinarily, metadata mutations are handled by the runtime epilogue, in `create_runtime_wrapper`. However, now that things are factored this way, the runtime wrapper operates only on synthetic bases instead of operating on the original inputs. For data mutations, it is fine to apply the data mutation to the synthetic base instead of the original input alias. But for metadata mutations, we **need** to apply the metadata mutation directly to the original inputs.

The way that I handled this was by tracking which inputs slot into this specific case (part of a synthetic base, and get metadata mutations), and updateing the flat_fn() that we pass downstream to return these updated inputs as extra outputs. From the perspective of downstream logic, these are real user outputs, that it can treat like any other user outputs. `aot_wrapper_synthetic_base` will know to grab these extra outputs and use them to apply the metadata mutations.

This was pretty annoying, but has the benefit that all of that logic is encapsulated entirely in `aot_wrapper_synthetic_base()`.

(2) input mutations are now performed on the synthetic base instead of the individual aliases.

You can see the original code comment [here](https://github.com/pytorch/pytorch/blob/b0b5f3c6c681896febbd9ff7ad7649b13def345d/torch/_functorch/aot_autograd.py#L1131) for details. We used to do the optimized thing in this case, and now we do the less optimized thing (copying the entire synthetic base, instead of the potentially smaller alias).

To be fair, we had no data showing that this optimization was showing improvements on any models in practice. I also think that the main reason anyone would ever run across this problem is because of a graph break - so if you care about perf, you probably want to avoid the extra graph breaks to begin with. I haven't added any warnings for this, but we probably could depending on what people think.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96235
Approved by: https://github.com/ezyang
2023-03-15 13:45:43 +00:00
Brian Hirsh 7a076b7b93 [aot_autograd] only performance functionalization analysis pass once (#95992)
For a while now, we've been re-running our functionalization analysis pass twice - once for get metadata when dedup'ing, and an entire second time during aot_dispatch_base/autograd.

This should also probably speed up compile times pretty noticeably, since we're going from:

(a) inference-only trace case: 3 fw traces -> 2 fw traces
(b) autograd trace case: 2 fw traces + 1 joint trace -> 1 fw trace + 1 joint trace

Pull Request resolved: https://github.com/pytorch/pytorch/pull/95992
Approved by: https://github.com/ezyang
2023-03-15 13:45:40 +00:00
PyTorch MergeBot e1ea584b1c Revert "[memory profiling] add a facility to gather combined C++/Python/TorchScript stack traces. (#95541)"
This reverts commit 4e1060c609.

Reverted https://github.com/pytorch/pytorch/pull/95541 on behalf of https://github.com/DanilBaibak due to breaking internal builds
2023-03-15 13:28:41 +00:00
Bin Bao 33c7be360f [reland][CI] switch torchbench to a pinned version (#96782)
Summary: This is reland of https://github.com/pytorch/pytorch/pull/96553

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96782
Approved by: https://github.com/huydhn
2023-03-15 12:46:36 +00:00
Nikita Vedeneev 3fd24fb608 COO intersection: allow external hash + hash reuse in sparse_mask (#94596)
External hash implies more flexibility in the op coverage + performance improvement.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/94596
Approved by: https://github.com/cpuhrsch
2023-03-15 09:11:14 +00:00
Kulin Seth 93f7996995 [MPS] Fix the MacOS 13.3 selector check. (#96733)
Fixes #ISSUE_NUMBER

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96733
Approved by: https://github.com/DenisVieriu97
2023-03-15 06:43:18 +00:00
BowenBao 60a68477a6 Bump black version to 23.1.0 (#96578)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96578
Approved by: https://github.com/ezyang
2023-03-15 06:27:59 +00:00
Nikita Shulga a229e78544 [BE] Enforce sign-compare (#96723)
Number of OSS PR were reverted, because new signed-unsigned comparison warnings, which are treated as errors in some internal builds.
Not sure how those selective rules are applied, but this PR removes `-Wno-sign-compare` from PyTorch codebase.

The only tricky part in this PR, as making sure that non-ASCII character detection works for both signed and unsigned chars  here:
https://github.com/pytorch/pytorch/blob/6e3d51b08ac108b27d892ab1be85eeb593ec1f0c/torch/csrc/jit/serialization/python_print.cpp#L926

Exclude several files from sign-compare if flash attention is used, due to the violation in cutlass, to be fixed by https://github.com/NVIDIA/cutlass/pull/869
Do not try to fix sign compare violations in caffe2 codebase
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96723
Approved by: https://github.com/albanD
2023-03-15 06:04:20 +00:00
Boris Fomitchev 96c745dfdc Fix int() casting in torch.nn.RNN to have correctly traced JIT and ONNX graph. (#92970)
Signed-off-by: Boris Fomitchev <bfomitchev@nvidia.com>

Fixes #91351

As for unit tests - in this PR I only fixed LSTM unit test to properly use dynamic axes and expose export issue by running test with same ONNX for additional inputs.
If the changes approved, we should also fix the rest of the tests (RNN/GRU and beyond).

I have verified the following updated tests are working with new code and failing with the old code:
test/onnx/test_pytorch_onnx_onnxruntime.py::TestONNXRuntime_opset_version_14_is_script_False_keep_initializers_as_inputs_True::test_rnn_name_lstm_nonlinearity_None_unilayer_bidirectional_no_initial_state_with_variable_length_sequences_with_dropout
test/onnx/test_pytorch_onnx_onnxruntime.py::TestONNXRuntime_opset_version_14_is_script_False_keep_initializers_as_inputs_True::test_rnn_name_lstm_nonlinearity_None_unilayer_bidirectional_with_initial_state_with_variable_length_sequences_with_dropout

Pull Request resolved: https://github.com/pytorch/pytorch/pull/92970
Approved by: https://github.com/titaiwangms, https://github.com/kit1980
2023-03-15 05:33:41 +00:00
PyTorch MergeBot d3a38bdd47 Revert "Update xnnpack to the latest commit (#95884)"
This reverts commit 0da89664cc.

Reverted https://github.com/pytorch/pytorch/pull/95884 on behalf of https://github.com/kit1980 due to Broke buck-build-test https://github.com/pytorch/pytorch/actions/runs/4421715166/jobs/7752808844#logs
2023-03-15 05:32:36 +00:00
Mark Saroufim 6110effa86 Rework torch.compile docs (#96706)
Chatted with @stas00 on slack and here are some great improvements he suggested to the compile docs

- [x] Rename `dynamo` folder to `compile`
- [x] Link `compile` docstring on `torch.html` to main index page for compile
- [x] Create a new index page that describes why people should care
  - [x] easy perf, memory reduction, 1 line
  - [x] Short benchmark table
  - [x] How to guide
  - [x] TOC that links to the more technical pages folks have written, make the existing docs we have a Technical overview
- [x] Highlight the new APIs for `torch._inductor.list_options()` and `torch._inductor.list_mode_options()` - clarify these are inductor specific and add more prose around which ones are most interesting

He also highlighted an interesting way to think about who is reading this doc we have

- [x] End users, that just want things to run fast
- [x] Library maintainers wrapping torch.compile which would care for example about understanding when in their code they should compile a model, which backends are supported
- [x] Debuggers who needs are somewhat addressed by the troubleshooting guide and faq but those could be dramatically reworked to say what we expect to break

And in a seperate PR I'll work on the below with @SherlockNoMad
- [ ] Authors of new backends that care about how to plug into dynamo or inductor layer so need to explain some more internals like
  - [ ] IR
  - [ ] Where to plugin, dynamo? inductor? triton?

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96706
Approved by: https://github.com/svekars
2023-03-15 04:41:13 +00:00
PyTorch MergeBot 2795233668 Revert "Fix periodic job by excluding check_graph_breaks (#96780)"
This reverts commit 8ec9beacec.

Reverted https://github.com/pytorch/pytorch/pull/96780 on behalf of https://github.com/wconstab due to broke trunk builds that didn't run on PR? didn't see those trunk failures on PR CI even with trunk label
2023-03-15 04:30:47 +00:00
Zachary DeVito 85639c1a88 [allocator] Generalize recording to a pool (#96542)
Previously the allocator would query whether a stream was recording a graph,
and look up the pool associated with a graph. This change has the allocator
directly associate a stream with a mempool, decoupling "record this stream to a pool"
from the action of "record all actions to a cuda graph".
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96542
Approved by: https://github.com/eellison
2023-03-15 04:28:49 +00:00
XiaobingSuper e01b092705 inductor: don't remember pre-loop order if pre loop has loop collapse (#96640)
Given the following case from timm **ese_vovnet19b_dw**:

```
import torch
import torch._dynamo

class Model(torch.nn.Module):
    def __init__(self):
        super(Model, self).__init__()
        self.conv1 = torch.nn.Conv2d(256, 256, kernel_size=1, padding=0)
        self.conv2 = torch.nn.Conv2d(256, 256, kernel_size=1, padding=0)
        self.pool = torch.nn.MaxPool2d(kernel_size=3, stride=2, ceil_mode=True)

    def forward(self, x):
        x = self.conv1(x)
        x2 = self.conv2(x)
        y = x2 * x
        return self.pool(y)

model = Model().to(memory_format=torch.channels_last).eval()
x = torch.randn(128, 256, 56, 56).to(memory_format=torch.channels_last)
opt_model = torch._dynamo.optimize('inductor')(model)
with torch.no_grad():
    for i in range(2):
        y = opt_model(x
```

before this PR, the max_pooling can't be vectorized:

```
extern "C" void kernel(float* in_out_ptr0,
                       const float* in_ptr0,
                       float* out_ptr0)
{
    #pragma omp parallel num_threads(40)
    {
        {
            #pragma omp for
            for(long i0=0; i0<6422528; i0+=1)
            {
                auto tmp0 = at::vec::Vectorized<float>::loadu(in_ptr0 + 16*i0);
                auto tmp1 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 16*i0);
                auto tmp2 = tmp0 * tmp1;
                tmp2.store(in_out_ptr0 + 16*i0);
            }
            #pragma omp for simd simdlen(8)
            for(long i0=102760448; i0<102760448; i0+=1)
            {
                auto tmp0 = in_ptr0[i0];
                auto tmp1 = in_out_ptr0[i0];
                auto tmp2 = tmp0 * tmp1;
                in_out_ptr0[i0] = tmp2;
            }
        }
        {
            #pragma omp for
            for(long i0=0; i0<128; i0+=1)
            {
                #pragma GCC ivdep
                for(long i1=0; i1<256; i1+=1)
                {
                    #pragma GCC ivdep
                    for(long i2=0; i2<28; i2+=1)
                    {
                        #pragma GCC ivdep
                        for(long i3=0; i3<28; i3+=1)
                        {
                            auto tmp0 = static_cast<long>(2*i2);
                            auto tmp1 = static_cast<long>(0);
                            auto tmp2 = tmp0 >= tmp1;
                            auto tmp3 = static_cast<long>(56);
                            auto tmp4 = tmp0 < tmp3;
                            auto tmp5 = tmp2 & tmp4;
                            auto tmp6 = static_cast<long>(2*i3);
                            auto tmp7 = tmp6 >= tmp1;
                            auto tmp8 = tmp6 < tmp3;
                            auto tmp9 = tmp7 & tmp8;
                            auto tmp10 = tmp5 & tmp9;
                            auto tmp11 = [&]
                            {
                                auto tmp12 = in_out_ptr0[i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp12;
                            }
                            ;
                            auto tmp13 = tmp10 ? tmp11() : -std::numeric_limits<decltype(tmp11())>::infinity();
                            auto tmp14 = static_cast<long>(1 + (2*i3));
                            auto tmp15 = tmp14 >= tmp1;
                            auto tmp16 = tmp14 < tmp3;
                            auto tmp17 = tmp15 & tmp16;
                            auto tmp18 = tmp5 & tmp17;
                            auto tmp19 = [&]
                            {
                                auto tmp20 = in_out_ptr0[256 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp20;
                            }
                            ;
                            auto tmp21 = tmp18 ? tmp19() : -std::numeric_limits<decltype(tmp19())>::infinity();
                            auto tmp22 = (tmp13 != tmp13) ? tmp13 : std::max(tmp21, tmp13);
                            auto tmp23 = static_cast<long>(2 + (2*i3));
                            auto tmp24 = tmp23 >= tmp1;
                            auto tmp25 = tmp23 < tmp3;
                            auto tmp26 = tmp24 & tmp25;
                            auto tmp27 = tmp5 & tmp26;
                            auto tmp28 = [&]
                            {
                                auto tmp29 = in_out_ptr0[512 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp29;
                            }
                            ;
                            auto tmp30 = tmp27 ? tmp28() : -std::numeric_limits<decltype(tmp28())>::infinity();
                            auto tmp31 = (tmp22 != tmp22) ? tmp22 : std::max(tmp30, tmp22);
                            auto tmp32 = static_cast<long>(1 + (2*i2));
                            auto tmp33 = tmp32 >= tmp1;
                            auto tmp34 = tmp32 < tmp3;
                            auto tmp35 = tmp33 & tmp34;
                            auto tmp36 = tmp35 & tmp9;
                            auto tmp37 = [&]
                            {
                                auto tmp38 = in_out_ptr0[14336 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp38;
                            }
                            ;
                            auto tmp39 = tmp36 ? tmp37() : -std::numeric_limits<decltype(tmp37())>::infinity();
                            auto tmp40 = (tmp31 != tmp31) ? tmp31 : std::max(tmp39, tmp31);
                            auto tmp41 = tmp35 & tmp17;
                            auto tmp42 = [&]
                            {
                                auto tmp43 = in_out_ptr0[14592 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp43;
                            }
                            ;
                            auto tmp44 = tmp41 ? tmp42() : -std::numeric_limits<decltype(tmp42())>::infinity();
                            auto tmp45 = (tmp40 != tmp40) ? tmp40 : std::max(tmp44, tmp40);
                            auto tmp46 = tmp35 & tmp26;
                            auto tmp47 = [&]
                            {
                                auto tmp48 = in_out_ptr0[14848 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp48;
                            }
                            ;
                            auto tmp49 = tmp46 ? tmp47() : -std::numeric_limits<decltype(tmp47())>::infinity();
                            auto tmp50 = (tmp45 != tmp45) ? tmp45 : std::max(tmp49, tmp45);
                            auto tmp51 = static_cast<long>(2 + (2*i2));
                            auto tmp52 = tmp51 >= tmp1;
                            auto tmp53 = tmp51 < tmp3;
                            auto tmp54 = tmp52 & tmp53;
                            auto tmp55 = tmp54 & tmp9;
                            auto tmp56 = [&]
                            {
                                auto tmp57 = in_out_ptr0[28672 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp57;
                            }
                            ;
                            auto tmp58 = tmp55 ? tmp56() : -std::numeric_limits<decltype(tmp56())>::infinity();
                            auto tmp59 = (tmp50 != tmp50) ? tmp50 : std::max(tmp58, tmp50);
                            auto tmp60 = tmp54 & tmp17;
                            auto tmp61 = [&]
                            {
                                auto tmp62 = in_out_ptr0[28928 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp62;
                            }
                            ;
                            auto tmp63 = tmp60 ? tmp61() : -std::numeric_limits<decltype(tmp61())>::infinity();
                            auto tmp64 = (tmp59 != tmp59) ? tmp59 : std::max(tmp63, tmp59);
                            auto tmp65 = tmp54 & tmp26;
                            auto tmp66 = [&]
                            {
                                auto tmp67 = in_out_ptr0[29184 + i1 + (512*i3) + (28672*i2) + (802816*i0)];
                                return tmp67;
                            }
                            ;
                            auto tmp68 = tmp65 ? tmp66() : -std::numeric_limits<decltype(tmp66())>::infinity();
                            auto tmp69 = (tmp64 != tmp64) ? tmp64 : std::max(tmp68, tmp64);
                            out_ptr0[i1 + (256*i3) + (7168*i2) + (200704*i0)] = tmp69;
                        }
                    }
                }
            }
        }
    }
}
''')
```

We always avoid reordering when pre-loop has a loop collapse: https://github.com/pytorch/pytorch/blob/2cbce06feebf5f52ef5539a3b1ae2e003217b6ac/torch/_inductor/ir.py#L2267-L2273.

This PR adds a check that only reuses pre-loop ordering when not having loop collapse.

After this PR, the generated code is
```

extern "C" void kernel(float* in_out_ptr0,
                       const float* in_ptr0,
                       float* out_ptr0)
{
    #pragma omp parallel num_threads(40)
    {
        {
            #pragma omp for
            for(long i0=0; i0<6422528; i0+=1)
            {
                auto tmp0 = at::vec::Vectorized<float>::loadu(in_ptr0 + 16*i0);
                auto tmp1 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 16*i0);
                auto tmp2 = tmp0 * tmp1;
                tmp2.store(in_out_ptr0 + 16*i0);
            }
            #pragma omp for simd simdlen(8)
            for(long i0=102760448; i0<102760448; i0+=1)
            {
                auto tmp0 = in_ptr0[i0];
                auto tmp1 = in_out_ptr0[i0];
                auto tmp2 = tmp0 * tmp1;
                in_out_ptr0[i0] = tmp2;
            }
        }
        {
            #pragma omp for
            for(long i0=0; i0<128; i0+=1)
            {
                #pragma GCC ivdep
                for(long i1=0; i1<28; i1+=1)
                {
                    #pragma GCC ivdep
                    for(long i2=0; i2<28; i2+=1)
                    {
                        for(long i3=0; i3<16; i3+=1)
                        {
                            auto tmp0 = at::vec::Vectorized<int>(static_cast<int>(2*i1));
                            auto tmp1 = at::vec::Vectorized<int>(static_cast<int>(0));
                            auto tmp2 = tmp0 >= tmp1;
                            auto tmp3 = at::vec::Vectorized<int>(static_cast<int>(56));
                            auto tmp4 = tmp0 < tmp3;
                            auto tmp5 = tmp2 & tmp4;
                            auto tmp6 = at::vec::Vectorized<int>(static_cast<int>(2*i2));
                            auto tmp7 = tmp6 >= tmp1;
                            auto tmp8 = tmp6 < tmp3;
                            auto tmp9 = tmp7 & tmp8;
                            auto tmp10 = tmp5 & tmp9;
                            auto tmp11 = [&]
                            {
                                auto tmp12 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp12;
                            }
                            ;
                            auto tmp13 = decltype(tmp11())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp11(), to_float_mask(tmp10) != at::vec::Vectorized<float>(0));
                            auto tmp14 = at::vec::Vectorized<int>(static_cast<int>(1 + (2*i2)));
                            auto tmp15 = tmp14 >= tmp1;
                            auto tmp16 = tmp14 < tmp3;
                            auto tmp17 = tmp15 & tmp16;
                            auto tmp18 = tmp5 & tmp17;
                            auto tmp19 = [&]
                            {
                                auto tmp20 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 256 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp20;
                            }
                            ;
                            auto tmp21 = decltype(tmp19())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp19(), to_float_mask(tmp18) != at::vec::Vectorized<float>(0));
                            auto tmp22 = at::vec::maximum(tmp21, tmp13);
                            auto tmp23 = at::vec::Vectorized<int>(static_cast<int>(2 + (2*i2)));
                            auto tmp24 = tmp23 >= tmp1;
                            auto tmp25 = tmp23 < tmp3;
                            auto tmp26 = tmp24 & tmp25;
                            auto tmp27 = tmp5 & tmp26;
                            auto tmp28 = [&]
                            {
                                auto tmp29 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 512 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp29;
                            }
                            ;
                            auto tmp30 = decltype(tmp28())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp28(), to_float_mask(tmp27) != at::vec::Vectorized<float>(0));
                            auto tmp31 = at::vec::maximum(tmp30, tmp22);
                            auto tmp32 = at::vec::Vectorized<int>(static_cast<int>(1 + (2*i1)));
                            auto tmp33 = tmp32 >= tmp1;
                            auto tmp34 = tmp32 < tmp3;
                            auto tmp35 = tmp33 & tmp34;
                            auto tmp36 = tmp35 & tmp9;
                            auto tmp37 = [&]
                            {
                                auto tmp38 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 14336 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp38;
                            }
                            ;
                            auto tmp39 = decltype(tmp37())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp37(), to_float_mask(tmp36) != at::vec::Vectorized<float>(0));
                            auto tmp40 = at::vec::maximum(tmp39, tmp31);
                            auto tmp41 = tmp35 & tmp17;
                            auto tmp42 = [&]
                            {
                                auto tmp43 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 14592 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp43;
                            }
                            ;
                            auto tmp44 = decltype(tmp42())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp42(), to_float_mask(tmp41) != at::vec::Vectorized<float>(0));
                            auto tmp45 = at::vec::maximum(tmp44, tmp40);
                            auto tmp46 = tmp35 & tmp26;
                            auto tmp47 = [&]
                            {
                                auto tmp48 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 14848 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp48;
                            }
                            ;
                            auto tmp49 = decltype(tmp47())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp47(), to_float_mask(tmp46) != at::vec::Vectorized<float>(0));
                            auto tmp50 = at::vec::maximum(tmp49, tmp45);
                            auto tmp51 = at::vec::Vectorized<int>(static_cast<int>(2 + (2*i1)));
                            auto tmp52 = tmp51 >= tmp1;
                            auto tmp53 = tmp51 < tmp3;
                            auto tmp54 = tmp52 & tmp53;
                            auto tmp55 = tmp54 & tmp9;
                            auto tmp56 = [&]
                            {
                                auto tmp57 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 28672 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp57;
                            }
                            ;
                            auto tmp58 = decltype(tmp56())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp56(), to_float_mask(tmp55) != at::vec::Vectorized<float>(0));
                            auto tmp59 = at::vec::maximum(tmp58, tmp50);
                            auto tmp60 = tmp54 & tmp17;
                            auto tmp61 = [&]
                            {
                                auto tmp62 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 28928 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp62;
                            }
                            ;
                            auto tmp63 = decltype(tmp61())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp61(), to_float_mask(tmp60) != at::vec::Vectorized<float>(0));
                            auto tmp64 = at::vec::maximum(tmp63, tmp59);
                            auto tmp65 = tmp54 & tmp26;
                            auto tmp66 = [&]
                            {
                                auto tmp67 = at::vec::Vectorized<float>::loadu(in_out_ptr0 + 29184 + (16*i3) + (512*i2) + (28672*i1) + (802816*i0));
                                return tmp67;
                            }
                            ;
                            auto tmp68 = decltype(tmp66())::blendv(at::vec::Vectorized<float>(-std::numeric_limits<float>::infinity()), tmp66(), to_float_mask(tmp65) != at::vec::Vectorized<float>(0));
                            auto tmp69 = at::vec::maximum(tmp68, tmp64);
                            tmp69.store(out_ptr0 + (16*i3) + (256*i2) + (7168*i1) + (200704*i0));
                        }
                        #pragma omp simd simdlen(8)
                        for(long i3=256; i3<256; i3+=1)
                        {
                            auto tmp0 = static_cast<long>(2*i1);
                            auto tmp1 = static_cast<long>(0);
                            auto tmp2 = tmp0 >= tmp1;
                            auto tmp3 = static_cast<long>(56);
                            auto tmp4 = tmp0 < tmp3;
                            auto tmp5 = tmp2 & tmp4;
                            auto tmp6 = static_cast<long>(2*i2);
                            auto tmp7 = tmp6 >= tmp1;
                            auto tmp8 = tmp6 < tmp3;
                            auto tmp9 = tmp7 & tmp8;
                            auto tmp10 = tmp5 & tmp9;
                            auto tmp11 = [&]
                            {
                                auto tmp12 = in_out_ptr0[i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp12;
                            }
                            ;
                            auto tmp13 = tmp10 ? tmp11() : -std::numeric_limits<decltype(tmp11())>::infinity();
                            auto tmp14 = static_cast<long>(1 + (2*i2));
                            auto tmp15 = tmp14 >= tmp1;
                            auto tmp16 = tmp14 < tmp3;
                            auto tmp17 = tmp15 & tmp16;
                            auto tmp18 = tmp5 & tmp17;
                            auto tmp19 = [&]
                            {
                                auto tmp20 = in_out_ptr0[256 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp20;
                            }
                            ;
                            auto tmp21 = tmp18 ? tmp19() : -std::numeric_limits<decltype(tmp19())>::infinity();
                            auto tmp22 = (tmp13 != tmp13) ? tmp13 : std::max(tmp21, tmp13);
                            auto tmp23 = static_cast<long>(2 + (2*i2));
                            auto tmp24 = tmp23 >= tmp1;
                            auto tmp25 = tmp23 < tmp3;
                            auto tmp26 = tmp24 & tmp25;
                            auto tmp27 = tmp5 & tmp26;
                            auto tmp28 = [&]
                            {
                                auto tmp29 = in_out_ptr0[512 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp29;
                            }
                            ;
                            auto tmp30 = tmp27 ? tmp28() : -std::numeric_limits<decltype(tmp28())>::infinity();
                            auto tmp31 = (tmp22 != tmp22) ? tmp22 : std::max(tmp30, tmp22);
                            auto tmp32 = static_cast<long>(1 + (2*i1));
                            auto tmp33 = tmp32 >= tmp1;
                            auto tmp34 = tmp32 < tmp3;
                            auto tmp35 = tmp33 & tmp34;
                            auto tmp36 = tmp35 & tmp9;
                            auto tmp37 = [&]
                            {
                                auto tmp38 = in_out_ptr0[14336 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp38;
                            }
                            ;
                            auto tmp39 = tmp36 ? tmp37() : -std::numeric_limits<decltype(tmp37())>::infinity();
                            auto tmp40 = (tmp31 != tmp31) ? tmp31 : std::max(tmp39, tmp31);
                            auto tmp41 = tmp35 & tmp17;
                            auto tmp42 = [&]
                            {
                                auto tmp43 = in_out_ptr0[14592 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp43;
                            }
                            ;
                            auto tmp44 = tmp41 ? tmp42() : -std::numeric_limits<decltype(tmp42())>::infinity();
                            auto tmp45 = (tmp40 != tmp40) ? tmp40 : std::max(tmp44, tmp40);
                            auto tmp46 = tmp35 & tmp26;
                            auto tmp47 = [&]
                            {
                                auto tmp48 = in_out_ptr0[14848 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp48;
                            }
                            ;
                            auto tmp49 = tmp46 ? tmp47() : -std::numeric_limits<decltype(tmp47())>::infinity();
                            auto tmp50 = (tmp45 != tmp45) ? tmp45 : std::max(tmp49, tmp45);
                            auto tmp51 = static_cast<long>(2 + (2*i1));
                            auto tmp52 = tmp51 >= tmp1;
                            auto tmp53 = tmp51 < tmp3;
                            auto tmp54 = tmp52 & tmp53;
                            auto tmp55 = tmp54 & tmp9;
                            auto tmp56 = [&]
                            {
                                auto tmp57 = in_out_ptr0[28672 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp57;
                            }
                            ;
                            auto tmp58 = tmp55 ? tmp56() : -std::numeric_limits<decltype(tmp56())>::infinity();
                            auto tmp59 = (tmp50 != tmp50) ? tmp50 : std::max(tmp58, tmp50);
                            auto tmp60 = tmp54 & tmp17;
                            auto tmp61 = [&]
                            {
                                auto tmp62 = in_out_ptr0[28928 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp62;
                            }
                            ;
                            auto tmp63 = tmp60 ? tmp61() : -std::numeric_limits<decltype(tmp61())>::infinity();
                            auto tmp64 = (tmp59 != tmp59) ? tmp59 : std::max(tmp63, tmp59);
                            auto tmp65 = tmp54 & tmp26;
                            auto tmp66 = [&]
                            {
                                auto tmp67 = in_out_ptr0[29184 + i3 + (512*i2) + (28672*i1) + (802816*i0)];
                                return tmp67;
                            }
                            ;
                            auto tmp68 = tmp65 ? tmp66() : -std::numeric_limits<decltype(tmp66())>::infinity();
                            auto tmp69 = (tmp64 != tmp64) ? tmp64 : std::max(tmp68, tmp64);
                            out_ptr0[i3 + (256*i2) + (7168*i1) + (200704*i0)] = tmp69;
                        }
                    }
                }
            }
        }
    }
```

After this PR, we can get a **18%** performance improvement for timm **ese_vovnet19b_dw** on skx-4148(```python -m torch.backends.xeon.run_cpu --node_id 0 benchmarks/dynamo/timm_models.py --performance --float32 -dcpu -n50 --inductor  --channels-last --no-skip --dashboard --only ese_vovnet19b_dw```):

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96640
Approved by: https://github.com/jgong5, https://github.com/EikanWang, https://github.com/jansel
2023-03-15 04:06:37 +00:00
PyTorch MergeBot c6a82e4339 [vision hash update] update the pinned vision hash (#96787)
This PR is auto-generated nightly by [this action](https://github.com/pytorch/pytorch/blob/master/.github/workflows/_update-commit-hash.yml).
Update the pinned vision hash.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96787
Approved by: https://github.com/pytorchbot
2023-03-15 03:05:28 +00:00
Will Constable 8ec9beacec Fix periodic job by excluding check_graph_breaks (#96780)
It's going to be harder to properly support check_graph_breaks
across multiple baselines.

Periodic and Inductor workflows are different baselines since they include
different sets of models.

It's not as simple as checking in the csv for the superset (periodic),
becuase `update_expected.py` is designed to run given the sha of your
failing PR and reset the baseline to that PR's artifacts.  This is a
nice workflow, and would be harder to manage if it had to always point to
a periodic job.

For now just do the check on the inductor job and ignore the other models
covered only on periodic.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96780
Approved by: https://github.com/malfet, https://github.com/huydhn
2023-03-15 02:54:53 +00:00
Matthias Braun 6d4d9840cd Stop including of PassManagerBuilder for llvm >= 15 (#96762)
Summary: LLVM trunk / llvm-16 removes the `PassManagerBuilder.h` file. But we are using the new pass manager for llvm>=15 anyway.

Test Plan: sandcastle

Differential Revision: D44064301

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96762
Approved by: https://github.com/bertmaher
2023-03-15 02:22:42 +00:00
PyTorch MergeBot a8f36dd646 Revert "add amp support for custom backend (#96188)"
This reverts commit cf12edee02.

Reverted https://github.com/pytorch/pytorch/pull/96188 on behalf of https://github.com/kit1980 due to Broke some linalg tests : https://github.com/pytorch/pytorch/actions/runs/4420037607/jobs/7750708339
2023-03-15 00:03:19 +00:00
Edward Z. Yang 5396f85c91 Propagate dynamo dynamic_shapes config to backwards (#96771)
This fixes

```
  File "/data/users/ezyang/a/pytorch/torch/_inductor/codegen/triton.py", line 1642, in codegen_node_schedule
    indexing_dtype_strength_reduction(node._body)
  File "/data/users/ezyang/a/pytorch/torch/_inductor/optimize_indexing.py", line 310, in indexing_dtype_strength_reduction
    OptimizeIndexing(loop_body, indices, indexing).run()
  File "/data/users/ezyang/a/pytorch/torch/_inductor/optimize_indexing.py", line 96, in __init__
    self.replace_indirect(k, ValueRanges(0, v))
  File "/data/users/ezyang/a/pytorch/torch/utils/_sympy/value_ranges.py", line 67, in __init__
    upper = simple_sympify(upper)
  File "/data/users/ezyang/a/pytorch/torch/utils/_sympy/value_ranges.py", line 33, in simple_sympify
    assert not e.free_symbols, f"free variables NYI: {e}"
AssertionError: free variables NYI: s0
```

Signed-off-by: Edward Z. Yang <ezyang@meta.com>

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96771
Approved by: https://github.com/eellison
2023-03-14 23:45:55 +00:00
Irem Yuksel 0da89664cc Update xnnpack to the latest commit (#95884)
After trying to update cpuinfo submodule to the latest, I saw that an update on xnnpack is also necessary.

Fixes the 2 failing checks on [#95379](https://github.com/pytorch/pytorch/pull/95379)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/95884
Approved by: https://github.com/Skylion007
2023-03-14 23:25:55 +00:00
Rohan Varma 707d892564 Debug logging around DDP mixed precision copies (#96438)
Per title

Differential Revision: [D43859976](https://our.internmc.facebook.com/intern/diff/D43859976/)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96438
Approved by: https://github.com/zhaojuanmao
2023-03-14 23:06:59 +00:00
Bin Bao b60d6e246e [inductor] Consolidate codegen functions in sizevars.py into wrapper.py (#96654)
Summary: Refactor the code so that wrapper codegen doesn't mix Python and C++.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96654
Approved by: https://github.com/jansel
2023-03-14 22:55:12 +00:00
Edward Z. Yang 037acd5a22 Update CI skips (#96745)
Signed-off-by: Edward Z. Yang <ezyang@meta.com>

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96745
Approved by: https://github.com/wconstab
2023-03-14 22:19:10 +00:00
Digant Desai a198ce6d76 [PyTorch][XNNPACK] Update build files for newly added kernels (#95911)
Same thing as D43747173 with some modifications to make sure internal only kernels are disabled in open source.

Differential Revision: [D43747173](https://our.internmc.facebook.com/intern/diff/D43747173/)

**NOTE FOR REVIEWERS**: This PR has internal Meta-specific changes or comments, please review them on [Phabricator](https://our.internmc.facebook.com/intern/diff/D43747173/)!
Pull Request resolved: https://github.com/pytorch/pytorch/pull/95911
Approved by: https://github.com/digantdesai
2023-03-14 22:13:24 +00:00
Aaron Gokaslan dd5e6e8553 [BE]: Merge startswith calls - rule PIE810 (#96754)
Merges startswith, endswith calls to into a single call that feeds in a tuple. Not only are these calls more readable, but it will be more efficient as it iterates through each string only once.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/96754
Approved by: https://github.com/ezyang
2023-03-14 22:05:20 +00:00
PyTorch MergeBot be4eaa69c2 Revert "[CI] switch torchbench to a pinned version (#96553)"
This reverts commit 61d6ccd29a.

Reverted https://github.com/pytorch/pytorch/pull/96553 on behalf of https://github.com/desertfire due to land race
2023-03-14 21:39:45 +00:00
PyTorch MergeBot 2951a75c3a Revert "Update perf smoke test threshold in check_hf_bert_perf_csv.py (#96772)"
This reverts commit 2eed44933b.

Reverted https://github.com/pytorch/pytorch/pull/96772 on behalf of https://github.com/desertfire due to land race
2023-03-14 21:37:30 +00:00
Yanbo Liang e7d795dccd [Inductor] aten.{avg_pool2d/max_pool2d_with_indices} arguments can be 1 element tuple (#96727)
Fixes failure from 14k github models: ```pytest ./generated/test_ProGamerGov_neural_dream.py -k test_000```
Error:
```
......
  File "/scratch/ybliang/work/repos/pytorch/torch/_inductor/graph.py", line 357, in call_function
    raise LoweringException(e, target, args, kwargs).with_traceback(
  File "/scratch/ybliang/work/repos/pytorch/torch/_inductor/graph.py", line 354, in call_function
    out = lowerings[target](*args, **kwargs)
  File "/scratch/ybliang/work/repos/pytorch/torch/_inductor/lowering.py", line 228, in wrapped
    out = decomp_fn(*args, **kwargs)
  File "/scratch/ybliang/work/repos/pytorch/torch/_inductor/lowering.py", line 3124, in avg_pool2d
    assert len(padding) == 2
torch._dynamo.exc.BackendCompilerFailed: backend='inductor' raised:
LoweringException: AssertionError:
  target: aten.avg_pool2d.default
  args[0]: TensorBox(StorageBox(
    InputBuffer(name='arg0_1', layout=FixedLayout('cuda', torch.float32, size=[4, 4, 64, 64], stride=[16384, 4096, 64, 1]))
  ))
  args[1]: [7, 7]
  args[2]: [1, 1]
  args[3]: [0]
  args[4]: False
  args[5]: False

```

Pull Request resolved: https://github.com/pytorch/pytorch/pull/96727
Approved by: https://github.com/jansel
2023-03-14 21:34:30 +00:00