Commit Graph

610 Commits

Author SHA1 Message Date
Mikayla Gawarecki afaee00fec Add python nested_tensor and as_nested_tensor constructors in torch.nested (#85593)
Remove `torch.nested_tensor` which has erroneous behavior wrt gradients (could be either leaf or not leaf). Introduce `torch.nested.nested_tensor` and `torch.nested.as_nested_tensor` in the vein of `torch.tensor` and `torch.as_tensor`. Done in nested `__init__.py` for now but can move to pybind in future (when we want to load from numpy/nested lists ).

Discussed offline with @cpuhrsch and pybind constructor (https://github.com/pytorch/pytorch/pull/85536) was more gnarly than expected, so we can move to that when we do need loading from numpy etc.

Differential Revision: [D39806622](https://our.internmc.facebook.com/intern/diff/D39806622)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/85593
Approved by: https://github.com/drisspg, https://github.com/cpuhrsch
2022-09-28 20:15:02 +00:00
Thomas Viehmann e41d758e26 Handle implicit real->complex casting for backward of stack (#84993)
Fixes: #75852

P.S.: Yay for the PyTorch foundation.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/84993
Approved by: https://github.com/soulitzer
2022-09-19 21:20:34 +00:00
Steven Krawczyk 89525cbd69 Add variable_list support to ExtractVariables struct (#84583)
This is required to unblock https://github.com/pytorch/xla/pull/3843, which lowers the einsum op for pytorch/xla.  Because one method input parameter is a TensorList, we need to support TensorLists here so that we can support einsum gradients.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/84583
Approved by: https://github.com/soulitzer
2022-09-16 01:26:22 +00:00
Edward Z. Yang ccade9410f Don't detach when making views; force caller to detach (#84893)
Signed-off-by: Edward Z. Yang <ezyang@fb.com>
Pull Request resolved: https://github.com/pytorch/pytorch/pull/84893
Approved by: https://github.com/soulitzer, https://github.com/SherlockNoMad
2022-09-14 22:32:45 +00:00
PyTorch MergeBot 8ca057eb71 Revert "Don't detach when making views; force caller to detach (#84893)"
This reverts commit 3bb8d6a93c.

Reverted https://github.com/pytorch/pytorch/pull/84893 on behalf of https://github.com/malfet due to Broke MPS, see https://hud.pytorch.org/pytorch/pytorch/commit/3bb8d6a93cc4cc4403dd2e3dfcd39b841c71a3c3
2022-09-14 01:09:04 +00:00
Edward Z. Yang 3bb8d6a93c Don't detach when making views; force caller to detach (#84893)
Signed-off-by: Edward Z. Yang <ezyang@fb.com>
Pull Request resolved: https://github.com/pytorch/pytorch/pull/84893
Approved by: https://github.com/soulitzer, https://github.com/SherlockNoMad
2022-09-13 23:31:21 +00:00
vfdev-5 d951165bd8 [C++ API] Added missing antialiasing path in interpolation C++ api (#84599)
Description:

Following https://github.com/pytorch/pytorch/pull/69318#issuecomment-1238433540 adding missing bicubic path for anti-alias flag to C++ frontend.

- https://github.com/pytorch/pytorch/pull/70930

- added tests in pytorch/test/cpp/api/functional.cpp

Pull Request resolved: https://github.com/pytorch/pytorch/pull/84599
Approved by: https://github.com/kit1980, https://github.com/malfet
2022-09-13 03:54:07 +00:00
Mikayla Gawarecki e217b30b0f Add torch.nested namespace (#84102)
First step towards #83775
- only `to_padded_tensor` is moved to the nested namespace for now
- following the schema used for `special`, `fft`, `linalg` and other namespaces, nested functions are registered in native_functions.yaml as `nested_{function_name}` and are bound to the desired Python name in
`torch/nested/__init__.py`, and the desired C++ name in `torch/csrc/api/include/torch/nested.h`.

~~**Question**: should we keep the documentation for `Tensor.to_padded_tensor` or can this deleted since it is shared by `torch.nested.to_padded_tensor`?~~

[generated nested docs](https://docs-preview.pytorch.org/84102/nested.html?highlight=nested#module-torch.nested)

Differential Revision: [D39361148](https://our.internmc.facebook.com/intern/diff/D39361148)
Pull Request resolved: https://github.com/pytorch/pytorch/pull/84102
Approved by: https://github.com/drisspg
2022-09-12 16:31:05 +00:00
Peter Bell b429a17545 Enable -Wunused-local-typedefs (#83708)
I recently had a PR reverted because it triggered an
unused-local-typedefs warning, so disabling these in the CMake build
is counter-productive.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/83708
Approved by: https://github.com/albanD
2022-08-26 15:45:47 +00:00
soulitzer 31fad3926a Add option to run anomaly mode without nan checking (#83481)
Fixes https://github.com/pytorch/pytorch/issues/83117

Pull Request resolved: https://github.com/pytorch/pytorch/pull/83481
Approved by: https://github.com/albanD
2022-08-16 22:56:23 +00:00
richard 382ef1fda7 Autograd graphtask trim unnecessary edges (#82544)
### Introduction
<!-- What did you change and why was it needed? -->

Removing unnecessary weight gradient calculation is very important for applications that need high-order derivatives during training. However, this is not supported by the current Autograd engine.

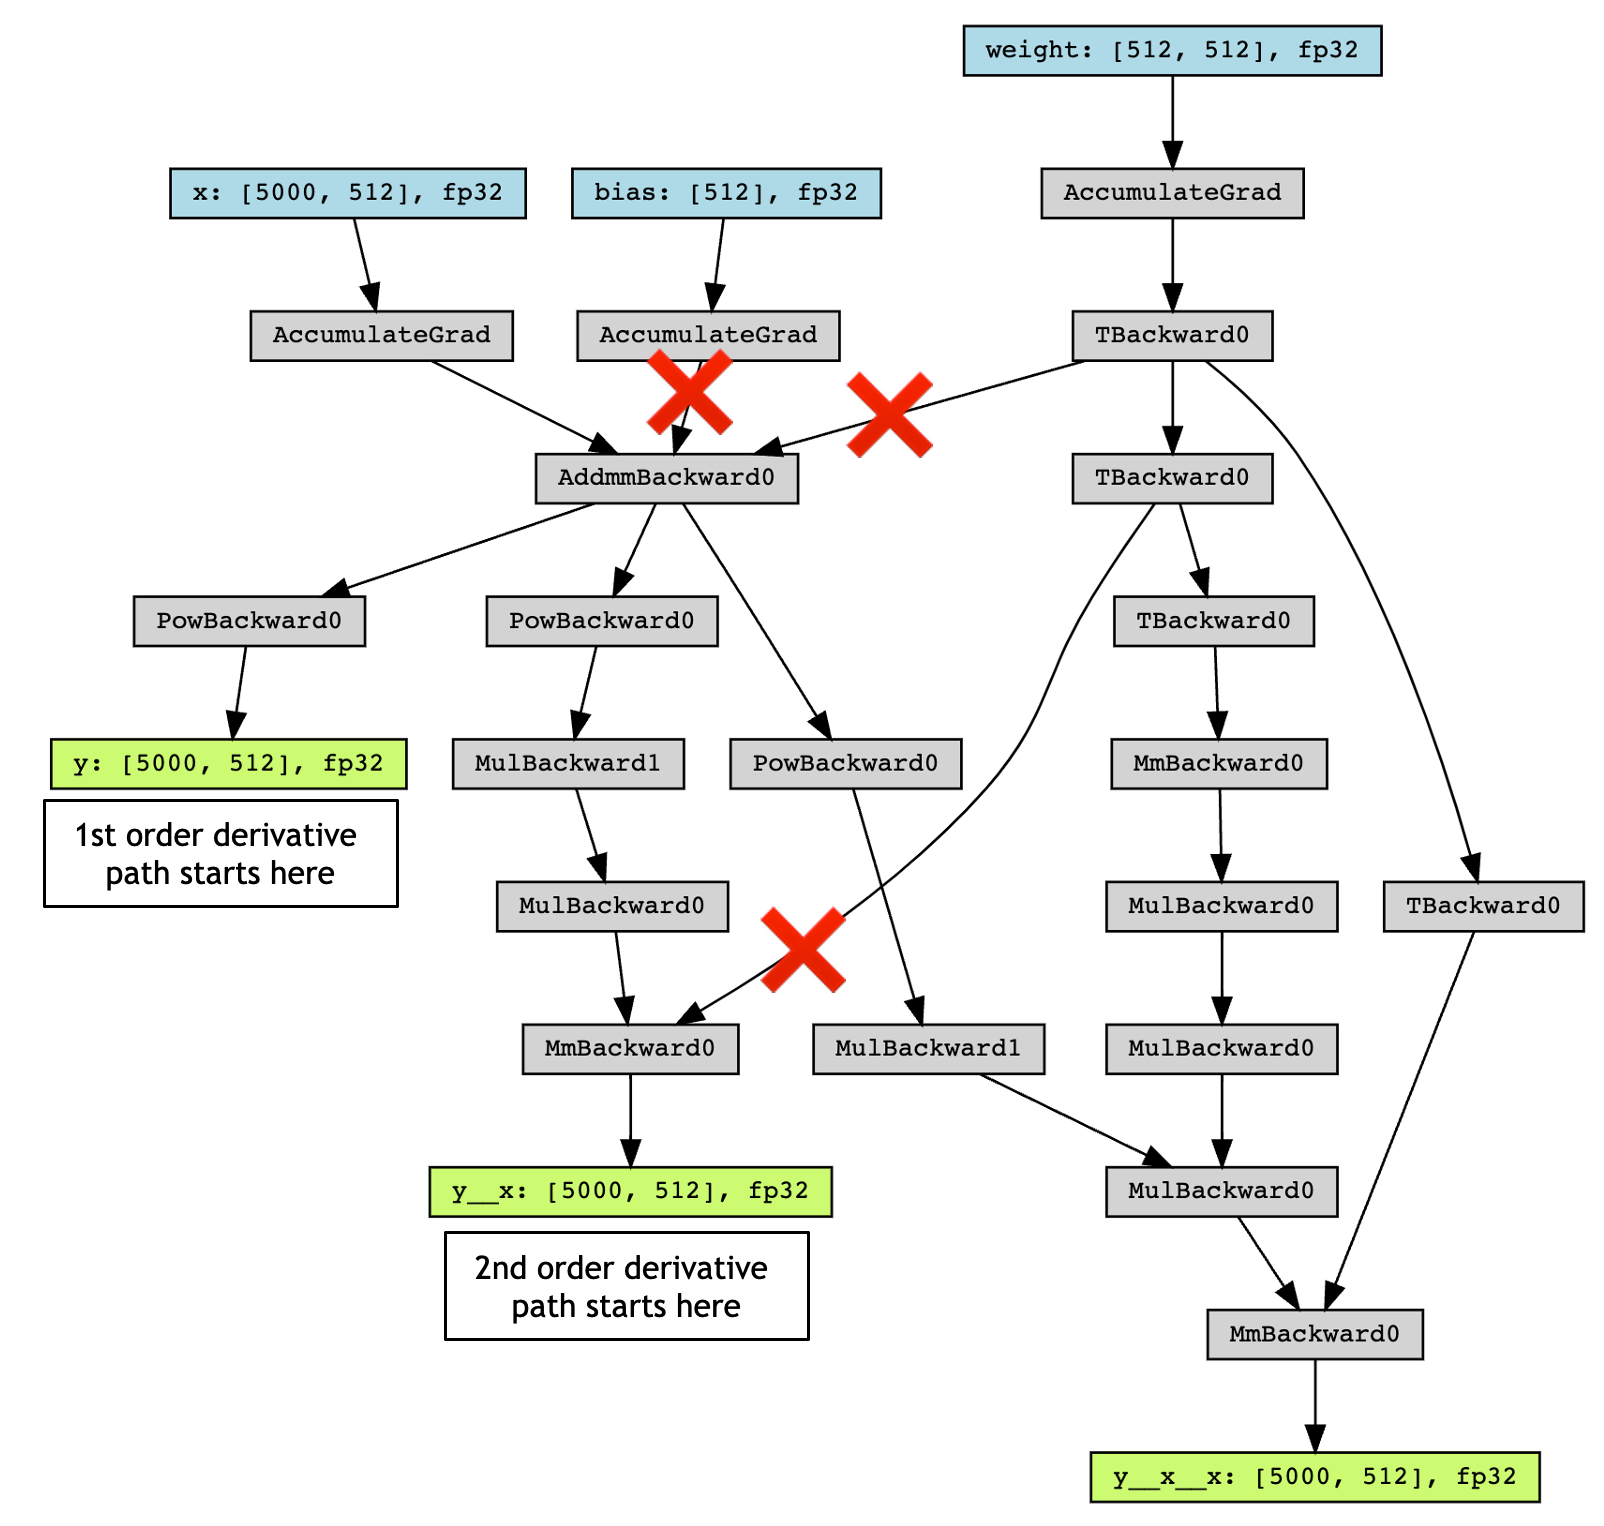
For more detail: The backward function of a `matmul` operator (e.g., `linear` `addmm` `mm`), has two matmuls, one for `input gradient` and another for `weight gradient`. For a typical neural network (nn) with a few linear layers and activation functions, if the user calls `torch.autograd.grad()` to calculate the derivative of the nn output `y` w.r.t the nn input `x`,  only the `input gradient` of the `matmul` operator is needed, and the `weight gradient` is discarded. However, the current PyTorch autograd engine will always calculate the `weight gradient` if `weight` requires gradient (the calculation of the high-order derivative is performed during training).

The figure attached shows the autograd graph of the following code snippet:
```py
y = torch.nn.functional.linear(x, weight, bias)
y = y.pow(2)
# first order derivative
y__x, = torch.autograd.grad(y, x, grad_outputs=grad_outputs, create_graph=True)
# first order derivative
y__x__x, = torch.autograd.grad(y__x, x, grad_outputs=grad_outputs, create_graph=True)
```
The path with ❌ is not needed when calculating derivatives.

<img width="50%" alt="image" src="https://user-images.githubusercontent.com/9999318/182018117-719c5a23-bcc6-4a63-8e8d-1bca3ebda2e3.png">

### Issue
<!-- Link to Issue ticket or RFP -->
Related issue: https://github.com/pytorch/pytorch/issues/56500

### Method
When calling `torch.autograd.grad`, `exec_info_` is created for each GraphTask, which allows filtering paths on the graph that are not needed. However, when the GraphTask calls into the node, the node still does not know whether the edges are needed or not. In the case of matmul, `weight.requires_grad is True` so the weight gradient is always calculated.

Following https://github.com/pytorch/pytorch/issues/56500#issuecomment-825694656, this PR passes the graph task's thread_local `exec_info_` into the node, so it could trim unnecessary edges during `torch.autograd.grad` calls.

### Benchmark
Benchmark script: https://gist.github.com/yueyericardo/24158433a2021c51eeef9c3e2722df99

Benchmark result:
6 hidden layers, batch size 10000, on A100

FP32 result
| hessian benchmark             | FP32 (before) | FP32 (After)      | FP32 (Functorch v0.1.1) |
| ----------------------------- | ------------- | ----------------- | ----------------------- |
| Linear + ReLU (no backward)   | 55.658 ms     | 29.392 ms (1.90X) | 29.547 ms (1.90X)       |
| Linear + ReLU (with backward) | 81.173 ms     | 54.917 ms (1.47X) | 68.988 ms (1.18X)       |

TF32 result
| hessian benchmark             | TF32 (before) | TF32 (after)      | TF32 (Functorch v0.1.1) |
| ----------------------------- | ------------- | ----------------- | ----------------------- |
| Linear + ReLU (no backward)   | 19.801 ms     | 11.259 ms (1.76X) | 10.754 ms (1.84X)       |
| Linear + ReLU (with backward) | 29.167 ms     | 20.466 ms (1.42X) | 22.784 ms (1.28X)       |

For FP32 result, we could get 1.9X speed up for hessian calculation, and 1.47X speed up during training, which is even faster than functorch `vmap(jacfwd(jacrev` implementation. (functorch has performance regression on v0.2.0, https://github.com/pytorch/functorch/issues/989, so we are using v0.1.1 for benchmark)

@zou3519 does functorch also includes similar optimizations during hessian calculation? If not, what do we need to do so the functorch could also benefit from this PR?

### Testing
<!-- How did you test your change? -->

- [x] we need to figure out a way for unittest

### Thanks
Thanks for the great blog: [How Computational Graphs are Executed in PyTorch | PyTorch](https://pytorch.org/blog/how-computational-graphs-are-executed-in-pytorch/)

cc @zasdfgbnm @albanD
Pull Request resolved: https://github.com/pytorch/pytorch/pull/82544
Approved by: https://github.com/soulitzer
2022-08-11 18:50:09 +00:00
Nikita Shulga 1b2a17b8f9 Build MacOS binaries with -Werror (#83049)
Should prevent proliferating MPS warnings
Fixes https://github.com/pytorch/pytorch/issues/82966
Pull Request resolved: https://github.com/pytorch/pytorch/pull/83049
Approved by: https://github.com/albanD, https://github.com/ezyang
2022-08-10 17:29:44 +00:00
Nikita Shulga 62c8d30f9f [BE] Add append_cxx_flag_if_supported macro (#82883)
And use it throughout the CMakeLists and rectify `IF(APPLE)`/`IF(GNU_CXX_VERSION VERSION_GREATER A.B)` and so on

Also, add `target_compile_options_if_supported` and use it in `Dependencies.cmake` as well as in test's `CMakeListst.txt`

Delete `-Wno-unknown-warning-option` to test that conditions indeed working as expected
Pull Request resolved: https://github.com/pytorch/pytorch/pull/82883
Approved by: https://github.com/seemethere
2022-08-10 14:32:26 +00:00
PyTorch MergeBot d3a1f17fc7 Revert "[BE] Add append_cxx_flag_if_supported macro (#82883)"
This reverts commit d7e6aaa59b.

Reverted https://github.com/pytorch/pytorch/pull/82883 on behalf of https://github.com/facebook-github-bot due to Diff reverted internally
2022-08-10 10:27:59 +00:00
Nikita Shulga d7e6aaa59b [BE] Add append_cxx_flag_if_supported macro (#82883)
And use it throughout the CMakeLists and rectify `IF(APPLE)`/`IF(GNU_CXX_VERSION VERSION_GREATER A.B)` and so on

Also, add `target_compile_options_if_supported` and use it in `Dependencies.cmake` as well as in test's `CMakeListst.txt`

Delete `-Wno-unknown-warning-option` to test that conditions indeed working as expected
Pull Request resolved: https://github.com/pytorch/pytorch/pull/82883
Approved by: https://github.com/seemethere
2022-08-08 21:04:09 +00:00
Peter Bell 8d0cbce069 Lower randint default dtype to the C++ API (#81410)
The default dtype for randint is currently handled with manual python
binding code, this moves it into the `native_functions.yaml` declaration
for API consistency.
Pull Request resolved: https://github.com/pytorch/pytorch/pull/81410
Approved by: https://github.com/albanD
2022-07-21 16:42:49 +00:00
soulitzer 516f3198d6 Fix retains grad behavior after in-place (#79996)
See this doc: https://docs.google.com/document/d/1KiRdnoj6B4cI3yl017hTbCqcOGO1gWIpUf20sldipHM/edit#

Two issues (1) regarding hooks in general and (2) regarding retains grad hooks are fixed, Python hooks, which rely on a different mechanism are not discussed here:
- Hooks in cpp in general
  - (fixed) new hooks to registered to a newer version of the tensor no longer get applied to grad_fn
    associated with older version of the tensor when the first hook was ever registered
  - (unchanged) hooks registered to the older version of the tensor remain active on
- Retains grad hooks
  - (fixed) now get moved to the latest grad_fn. NB: To the user, retains_grad is not considered hooks
    or expected to behave like hooks (which we consider properties of the grad_fn) vs retains_gradness
    which is a property of the tensor.
- (not in this PR) Python hooks
  - (will fix) same issue as hooks in cpp where new hooks are being applied to grad_fn associated
    with the older version of the tensor
Pull Request resolved: https://github.com/pytorch/pytorch/pull/79996
Approved by: https://github.com/albanD
2022-07-08 19:13:28 +00:00
Sergei Vorobev a8b0988596 Fix //:module_test Conversion_MultiCUDA (#79926)
Fixes #79871

Make `module.cpp` tests respect change that was made in #78436 (no int types in autograd).

Note that there still a gap in Cmake test -- it's unclear why it didn't fail CI before.

As far as I can tell it should be executed, because it's included here https://github.com/pytorch/pytorch/blob/79507d2a9d06d4a3fb50eb21b30e08cc044776ce/test/cpp/api/CMakeLists.txt#L17:L17

Pull Request resolved: https://github.com/pytorch/pytorch/pull/79926
Approved by: https://github.com/soulitzer
2022-06-21 23:32:18 +00:00
Michael Suo 30fb2c4aba [lint] autoformat test/cpp and torch/csrc
Let's have some fun.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/78828

Approved by: https://github.com/ezyang
2022-06-11 21:11:16 +00:00
Michael Andreas Dagitses ab2ca95dd1 turn on -Werror=unused-variable in our Bazel CPU build
Summary:
We also fix any existing issues. Note that we only do this for the CPU
build because nvcc is considered a C++ toolchain but it does not have
the same flag support. Adding flags to the GPU build will cause nvcc
errors.

Test Plan: Built locally, rely on CI to confirm.

Reviewers: malfet

Subscribers:

Tasks:

Tags:

Pull Request resolved: https://github.com/pytorch/pytorch/pull/79156

Approved by: https://github.com/seemethere, https://github.com/osalpekar, https://github.com/albanD
2022-06-11 02:46:34 +00:00
Nikita Shulga 3255ddeec9 Make Wunused-local-typedef a hard error (#77918)
Only allow it for `libtorch_python` and tests
Helps prevent regression like https://github.com/pytorch/pytorch/pull/76547#issuecomment-1132208232

Pull Request resolved: https://github.com/pytorch/pytorch/pull/77918
Approved by: https://github.com/osalpekar, https://github.com/seemethere
2022-06-09 18:14:01 +00:00
yanbing-j 4f82f439d1 Enable BFloat16 ELU, SELU and CELU in CPU path (#62546)
Enable BFloat16 ELU, SELU and CELU in CPU path. SELU and CELU will call ELU implementation.

Pull Request resolved: https://github.com/pytorch/pytorch/pull/62546
Approved by: https://github.com/frank-wei
2022-05-12 16:56:57 +00:00
Pavithran Ramachandran f984e50f39 Extend jit::load to work on flatbuffer file; Take 2 (#75256)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/75256

ghstack-source-id: 153138970

Test Plan: CI

Reviewed By: iseeyuan

Differential Revision: D35399581

fbshipit-source-id: dafe9d301009d3f70986ed92bfe06d160ab90ba0
(cherry picked from commit ccc860fd07)
2022-04-06 17:54:01 +00:00
Lu Fang 32e58c73c4 Back out "Extend jit::load to work on flatbuffer file" (#75244)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/75244

Original commit changeset: d653a5af662a

Original Phabricator Diff: D35060736 (https://github.com/pytorch/pytorch/commit/d9d34922a08af88f0dc68ad7ebe353990ebc1226)

Test Plan: Model loading test, verified that D35060736 (https://github.com/pytorch/pytorch/commit/d9d34922a08af88f0dc68ad7ebe353990ebc1226) will cause the torch::save => torch::load failure.

Reviewed By: yinghai, jianyuh

Differential Revision: D35387009

fbshipit-source-id: 9d176992d402d57779e2af3d905b3c1538335298
(cherry picked from commit 6c8cc0d3b8)
2022-04-05 09:55:04 +00:00
Nikita Shulga 81d765ef1f Fix sign-compare violations in cpp tests
Prerequisite change for enabling `-Werror=sign-compare` across PyTorch repo

Pull Request resolved: https://github.com/pytorch/pytorch/pull/75080

Approved by: https://github.com/atalman
2022-04-04 23:05:31 +00:00
Pavithran Ramachandran d9d34922a0 Extend jit::load to work on flatbuffer file (#75022)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/75022

Extending torch::jit::load to read flatbuffer file
ghstack-source-id: 152820697

Test Plan: CI

Reviewed By: iseeyuan

Differential Revision: D35060736

fbshipit-source-id: d653a5af662a46107ff4fd70209fd2a0a4d40f20
(cherry picked from commit 109e14a54b)
2022-04-02 01:33:34 +00:00
Kurt Mohler 5375b2e994 Resolve int[]? arguments to new OptionalIntArrayRef class
This PR uses the `OptionalArrayRef` template class that was drafted in #64084.

Fixes #44409
Pull Request resolved: https://github.com/pytorch/pytorch/pull/70864
Approved by: https://github.com/ezyang
2022-03-26 01:45:50 +00:00
Yedidya Feldblum 7a5b0efc64 [caffe2] fix build failures in optimized builds under clang
Summary:
There are various possible approaches, but the approach chosen minimizes disruption to source control blame.

Addresses:
```
error: Function _ZN23FunctionalTest_Pad_Test8TestBodyEv is too big to optimize [-Werror,-Wignored-optimization-argument]
```

Test Plan: buck2 build mode/opt caffe2/test/cpp/api:functional

Reviewed By: jamesr66a

Differential Revision: D34027291

fbshipit-source-id: 9dfd771ad56d3d4bc0d41b38b04654c8dae7c006
(cherry picked from commit d43b5a7ed6)
2022-02-22 22:31:47 +00:00
Ryan Spring 4f8b986e28 Implement Tanh Gelu Approximation (#61439)
Summary:
1. Implements https://github.com/pytorch/pytorch/issues/39853
2. Adds approximate boolean flag to Gelu
3. Enables Tanh Gelu approximation
4. Adds double backward support for Gelu
5. Enable Tanh Gelu in NvFuser

```
def gelu(x, approximate : str = 'none'):
    if approximate == 'tanh':
        # sqrt(2/pi) = 0.7978845608028654
        return 0.5 * x * (1.0 + torch.tanh(0.7978845608028654 * (x + 0.044715 * torch.pow(x, 3.0))))
    else:
        return x * normcdf(x)
```

Linking XLA PR - https://github.com/pytorch/xla/pull/3039

Pull Request resolved: https://github.com/pytorch/pytorch/pull/61439

Reviewed By: VitalyFedyunin

Differential Revision: D33894937

Pulled By: jbschlosser

fbshipit-source-id: b65e8fb6ea66168af8f34f45ed50e92737a33851
(cherry picked from commit 6e986f91a9)
2022-02-14 03:40:32 +00:00
kshitij12345 02f6226bff [fix] Dropout2d-3d no-batch-dim (#69885)
Summary:
Fixes https://github.com/pytorch/pytorch/issues/69801

TODO:
* [x] Update C++ API

cc albanD mruberry jbschlosser walterddr kshitij12345

Pull Request resolved: https://github.com/pytorch/pytorch/pull/69885

Reviewed By: mruberry

Differential Revision: D33175470

Pulled By: jbschlosser

fbshipit-source-id: c9d7d9e0f59ba290a0157725c338a345f3d58b9f
(cherry picked from commit 7e4271a156)
2022-02-02 16:40:32 +00:00
Nikita Shulga 74c44ba9d6 Revert D33850228: [pytorch][PR] Implement Tanh Gelu Approximation
Test Plan: revert-hammer

Differential Revision:
D33850228 (https://github.com/pytorch/pytorch/commit/23d03025dc870a26c63a9d0e01aa59f644fd6cbe)

Original commit changeset: 3cc33fb298e4

Original Phabricator Diff: D33850228 (https://github.com/pytorch/pytorch/commit/23d03025dc870a26c63a9d0e01aa59f644fd6cbe)

fbshipit-source-id: 9436e7df73c2b2e2011f321674f24973316d3692
(cherry picked from commit c9efb58223)
2022-01-31 17:44:19 +00:00
Ryan Spring 23d03025dc Implement Tanh Gelu Approximation (#61439)
Summary:
1. Implements https://github.com/pytorch/pytorch/issues/39853
2. Adds approximate boolean flag to Gelu
3. Enables Tanh Gelu approximation
4. Adds double backward support for Gelu
5. Enable Tanh Gelu in NvFuser

```
def gelu(x, approximate : str = 'none'):
    if approximate == 'tanh':
        # sqrt(2/pi) = 0.7978845608028654
        return 0.5 * x * (1.0 + torch.tanh(0.7978845608028654 * (x + 0.044715 * torch.pow(x, 3.0))))
    else:
        return x * normcdf(x)
```

Linking XLA PR - https://github.com/pytorch/xla/pull/3039

Pull Request resolved: https://github.com/pytorch/pytorch/pull/61439

Reviewed By: cpuhrsch

Differential Revision: D33850228

Pulled By: jbschlosser

fbshipit-source-id: 3cc33fb298e480d7ecc5c67716da019d60c6ab33
(cherry picked from commit 3a53b3e94f)
2022-01-31 17:07:45 +00:00
Joel Schlosser cb823d9f07 Revert D33744717: [pytorch][PR] Implement Tanh Gelu Approximation
Test Plan: revert-hammer

Differential Revision:
D33744717 (https://github.com/pytorch/pytorch/commit/f499ab9ceff49be0b64a15020103c6baec3387ea)

Original commit changeset: d64532a562ed

Original Phabricator Diff: D33744717 (https://github.com/pytorch/pytorch/commit/f499ab9ceff49be0b64a15020103c6baec3387ea)

fbshipit-source-id: 396c3f63de5865f894dbc353d0790a01a624be93
(cherry picked from commit e9fb2d1db1)
2022-01-28 18:35:01 +00:00
Ryan Spring f499ab9cef Implement Tanh Gelu Approximation (#61439)
Summary:
1. Implements https://github.com/pytorch/pytorch/issues/39853
2. Adds approximate boolean flag to Gelu
3. Enables Tanh Gelu approximation
4. Adds double backward support for Gelu
5. Enable Tanh Gelu in NvFuser

```
def gelu(x, approximate : str = 'none'):
    if approximate == 'tanh':
        # sqrt(2/pi) = 0.7978845608028654
        return 0.5 * x * (1.0 + torch.tanh(0.7978845608028654 * (x + 0.044715 * torch.pow(x, 3.0))))
    else:
        return x * normcdf(x)
```

Linking XLA PR - https://github.com/pytorch/xla/pull/3039

Pull Request resolved: https://github.com/pytorch/pytorch/pull/61439

Reviewed By: mikaylagawarecki

Differential Revision: D33744717

Pulled By: jbschlosser

fbshipit-source-id: d64532a562ed53247bb4fa52bb16722634d5c187
(cherry picked from commit 4713dd9cca)
2022-01-28 16:59:09 +00:00
Joel Schlosser e6befbe85c Add flag to optionally average output attention weights across heads (#70055)
Summary:
Fixes https://github.com/pytorch/pytorch/issues/47583

Pull Request resolved: https://github.com/pytorch/pytorch/pull/70055

Reviewed By: bhosmer

Differential Revision: D33457866

Pulled By: jbschlosser

fbshipit-source-id: 17746b3668b0148c1e1ed8333227b7c42f1e3bf5
2022-01-06 17:32:37 -08:00
George Qi 8af39b7668 AdaptiveLogSoftmaxWithLoss no_batch_dim support (#69054)
Summary: Pull Request resolved: https://github.com/pytorch/pytorch/pull/69054

Test Plan: Imported from OSS

Reviewed By: jbschlosser

Differential Revision: D33200166

Pulled By: george-qi

fbshipit-source-id: 9d953744351a25f372418d2a64e8402356d1e9b7
2021-12-29 10:25:26 -08:00
vfdev-5 ce9a2f8ba9 [C++ API] Added missing nearest-exact mode and anti-alias flag (#69318)
Summary:
Description:

Following https://github.com/pytorch/pytorch/pull/65142#issuecomment-981995692 adding missing nearest-exact mode and anti-alias flag to C++ frontend.

- https://github.com/pytorch/pytorch/pull/65142
- https://github.com/pytorch/pytorch/pull/64501

- added tests in pytorch/test/cpp/api/functional.cpp

Pull Request resolved: https://github.com/pytorch/pytorch/pull/69318

Reviewed By: davidberard98

Differential Revision: D33278995

Pulled By: jbschlosser

fbshipit-source-id: fa87c0c78df6b398e4f9688cc02111eed187afa7
2021-12-22 11:10:51 -08:00
George Qi bb51519937 bug fix FractionalMaxPool2d (random_samples dimensions) (#70031)
Summary: Pull Request resolved: https://github.com/pytorch/pytorch/pull/70031

Test Plan: Imported from OSS

Reviewed By: ejguan

Differential Revision: D33200618

Pulled By: george-qi

fbshipit-source-id: 142f224c2cab1008d2d4e9ed333697a92d2d42db
2021-12-21 12:21:54 -08:00
Richard Barnes afb742382a use irange for loops 10 (#69394)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/69394

Modified loops in files under fbsource/fbcode/caffe2/ from the format
```
for(TYPE var=x0;var<x_max;x++)
```
to the format
```
for(const auto var: irange(xmax))
```

This was achieved by running r-barnes's loop upgrader script (D28874212) with some modification to exclude all files under /torch/jit and a number of reversions or unused variable suppression warnings added by hand.

Test Plan: Sandcastle

Reviewed By: malfet

Differential Revision: D32837991

fbshipit-source-id: fc7c4f76d2f32a17a0faf329294b3fe7cb81df32
2021-12-09 09:49:34 -08:00
Ramanpreet Nara f587267dc7 Revert D31705359: use irange for loops 8
Test Plan: revert-hammer

Differential Revision:
D31705359 (https://github.com/pytorch/pytorch/commit/17e52004410453bcc490087917ca163efd819695)

Original commit changeset: c9ea2fbc0f9c

fbshipit-source-id: 08fff2d12beca953ad30dd0baabf86e39ac84f14
2021-12-02 12:55:08 -08:00
Richard Barnes 17e5200441 use irange for loops 8 (#66743)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/66743

Modified loops in files under fbsource/fbcode/caffe2/ from the format

`for(TYPE var=x0;var<x_max;x++)`

to the format

`for(const auto var: irange(xmax))`

This was achieved by running r-barnes's loop upgrader script (D28874212) with some modification to exclude all files under /torch/jit and a number of reversions or unused variable suppression warnings added by hand.

Test Plan: Sandcastle

Reviewed By: malfet

Differential Revision: D31705359

fbshipit-source-id: c9ea2fbc0f9cd29e97a52dcb203addc5f2abb09b
2021-12-02 10:21:29 -08:00
Vinnam Kim 7b701ce2d4 Add set_to_none option to C++ API (#68801)
Summary:
Fixes https://github.com/pytorch/pytorch/issues/68167.

Signed-off-by: Vinnam Kim <vinnam.kim@makinarocks.ai>

Pull Request resolved: https://github.com/pytorch/pytorch/pull/68801

Reviewed By: mruberry

Differential Revision: D32625239

Pulled By: jbschlosser

fbshipit-source-id: 5f09b959e23d5448106a47029d06ec20ad094d82
2021-11-29 08:42:39 -08:00
Pavithran Ramachandran 1ce500f56f [easy][PyTorch] Use at::native::is_nonzero (#67195)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/67195

Now that `is_nonzero` is part of `at::native` refer https://github.com/pytorch/pytorch/pull/66663, replacing `TensorCompare::is_nonzero` to `at::native::is_nonzero`

ghstack-source-id: 141514416

Test Plan: CI

Reviewed By: larryliu0820

Differential Revision: D31704041

fbshipit-source-id: 36813e5411d0aa2eb2d0442e2a195bbed417b33d
2021-10-26 12:40:32 -07:00
Richard Barnes e0643fa3fc use irange for loops 5 (#66744)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/66744

Modified loops in files under fbsource/fbcode/caffe2/ from the format

`for(TYPE var=x0;var<x_max;x++)`

to the format

`for(const auto var: irange(xmax))`

This was achieved by running r-barnes's loop upgrader script (D28874212) with some modification to exclude all files under /torch/jit and a number of reversions or unused variable suppression warnings added by hand.

Test Plan: Sandcastle

Reviewed By: ngimel

Differential Revision: D31705358

fbshipit-source-id: d6ea350cbaa8f452fc78f238160e5374be637a48
2021-10-18 21:59:50 -07:00
Xue Li 2f099c7555 Revert D30652629: use irange for loops
Test Plan: revert-hammer

Differential Revision:
D30652629 (https://github.com/pytorch/pytorch/commit/687c2267d4dfb69138483f90deb4d4f5921a2965)

Original commit changeset: 0ae6c4bbbb55

fbshipit-source-id: 5c4f067b584a021c8c9656454d1ee60999600fb3
2021-10-15 15:23:10 -07:00
Richard Barnes 687c2267d4 use irange for loops (#66234)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/66234

Modified loops in files under fbsource/fbcode/caffe2/ from the format

`for(TYPE var=x0;var<x_max;x++)`

to the format

`for(const auto var: irange(xmax))`

This was achieved by running r-barnes's loop upgrader script (D28874212) with some modification to exclude all files under /torch/jit and a number of reversions or unused variable suppression warnings added by hand.

bypass_size_limit
allow-large-files

Test Plan: Sandcastle

Reviewed By: ngimel

Differential Revision: D30652629

fbshipit-source-id: 0ae6c4bbbb554bad42e372792a6430e1acf15e3e
2021-10-15 13:50:33 -07:00
soulitzer 93d326c868 Add InplaceOrView boxed kernel (#63878)
Summary:
Pull Request resolved: https://github.com/pytorch/pytorch/pull/63878

See https://github.com/pytorch/pytorch/issues/64407, https://github.com/pytorch/pytorch/issues/62032 for context:

In this PR:
 - Add boxed kernel by replicating `gen_inplace_or_view`'s logic that is ONLY for use with the Autograd not-implemented kernel
   - Unlike `gen_inplace_or_view` we always pass a view_func to as_view in order to ensure that an "derivative is not implemented" error is raised even if an in-place update is performed on the view. Without the `view_func`, the CopySlice + AsStridedBackward nodes would replace the NotImplemented node.
   - This limitation makes it impossible to use this node for general use
   - view relationship must be between first input (must be tensor) and first output (may be tensor or vec of tensor)
   - do not support non-differentiable views (_values, _indices, view.dtype) - view relationship is always fw and bw differentiable
 - Adds the macro `#define REGISTER_AUTOGRAD_NOT_IMPLEMENTED_FALLBACK(ns, op)` to be the interface for this feature:
   - static initialization can be slowed down(? not measured) if there are many registrations, because each line translates to 2 library calls but the workaround is just to manually use the two functions `AutogradNotImplementedFallback` and `ADInplaceOrViewFallback` and call `m.impl`.
 - Adds testing:
    - for views: view relationship created
      -  performing in-place operation on the view, raises properly
      - trying to create two view relationships is not allowed,
      - single view relationship but not first input/first output should error
      - view relation created properly for tensor vector output
    - for in-place:
      - version count bump
      - triggers rebase_history
      - multiple mutations is okay and also updates version counter
 - TODO (follow up): Update tutorials for adding  third-party operators (and document the above limitations)
 - TODO (follow up): Look at torch-audio/torch-vision and identify places where this can simplify existing code

EDIT: Made it more clear what is introduced in this PR and moved some more contextual stuff into the issue itself

Test Plan: Imported from OSS

Reviewed By: albanD

Differential Revision: D30901714

Pulled By: soulitzer

fbshipit-source-id: 48de14c28be023ff4bd31b7ea5e7cba88aeee04c
2021-10-12 18:55:50 -07:00
Nikita Shulga 4c4525fa5c Compile without -Wno-unused-variable (take 2) (#66041)
Summary:
Delete `-Wno-unused-variable` from top level `CMakeLists.txt`
Still suppress those warnings for tests and `torch_python`

Delete number of unused variables from caffe2 code
Use `(void)var;` to suppress unused variable in range loops
Use `C10_UNUSED` for global constructors and use `constexpr` instead of `static` for global constants

Do not delete `caffe2::OperatorBase::Output` calls as they have side effects

Pull Request resolved: https://github.com/pytorch/pytorch/pull/66041

Reviewed By: ngimel

Differential Revision: D31360142

Pulled By: malfet

fbshipit-source-id: 6fdfb9f91efdc49ca984a2f2a17ee377d28210c8
2021-10-04 20:39:39 -07:00
Nikita Shulga e4ee5ca698 Revert D31326599: [pytorch][PR] Compile without -Wno-unused-variable
Test Plan: revert-hammer

Differential Revision:
D31326599 (https://github.com/pytorch/pytorch/commit/a6280ab653efbf3c22e9f2dcc0dde7d22edc9a92)

Original commit changeset: 924155f1257a

fbshipit-source-id: b8ee5bc0298637443232f5ee9ec79e51ed256faf
2021-10-01 20:40:47 -07:00
Nikita Shulga a6280ab653 Compile without -Wno-unused-variable (#65954)
Summary:
Delete `-Wno-unused-variable` from top level `CMakeLists.txt`
Still suppress those warnings for tests and `torch_python`

Delete number of unused variables from caffe2 code
Use `(void)var;` to suppress unused variable in range loops
Use `C10_UNUSED` for global constructors and use `constexpr` instead of `static` for global constants

Pull Request resolved: https://github.com/pytorch/pytorch/pull/65954

Reviewed By: ngimel

Differential Revision: D31326599

Pulled By: malfet

fbshipit-source-id: 924155f1257a2ba1896c50512f615e45ca1f61f3
2021-10-01 17:40:47 -07:00